FlyNava Insights
Insights and perspectives on airline pricing, revenue management, AI and continuous pricing.
Aviation Pricing Just Got Faster. Jupiter 5.5's QA Results Make the Case
How Jupiter 5.5 was tested for reliability, responsiveness, and enterprise-scale performance for modern airline pricing operations.
In aviation pricing, the systems you rely on rarely make headlines — until they fail.
A fare update that doesn't propagate. An API timeout during a flash sale. A pricing engine that lags during a competitor's capacity dump. These aren't hypothetical risks. They're the operational realities that separate pricing teams that move fast from those that spend their days firefighting.
Jupiter 5.5 recently completed enterprise-scale QA testing. The results are worth examining carefully — not because the numbers are uniformly impressive, but because of what they reveal how the platform behaves under real pressure.
I. What the Testing Actually Measured
The QA suite ran 5,600 system checks across 20 concurrent virtual users, simulating the kind of multi-user load a mid-to-large airline pricing team produces during active commercial periods.
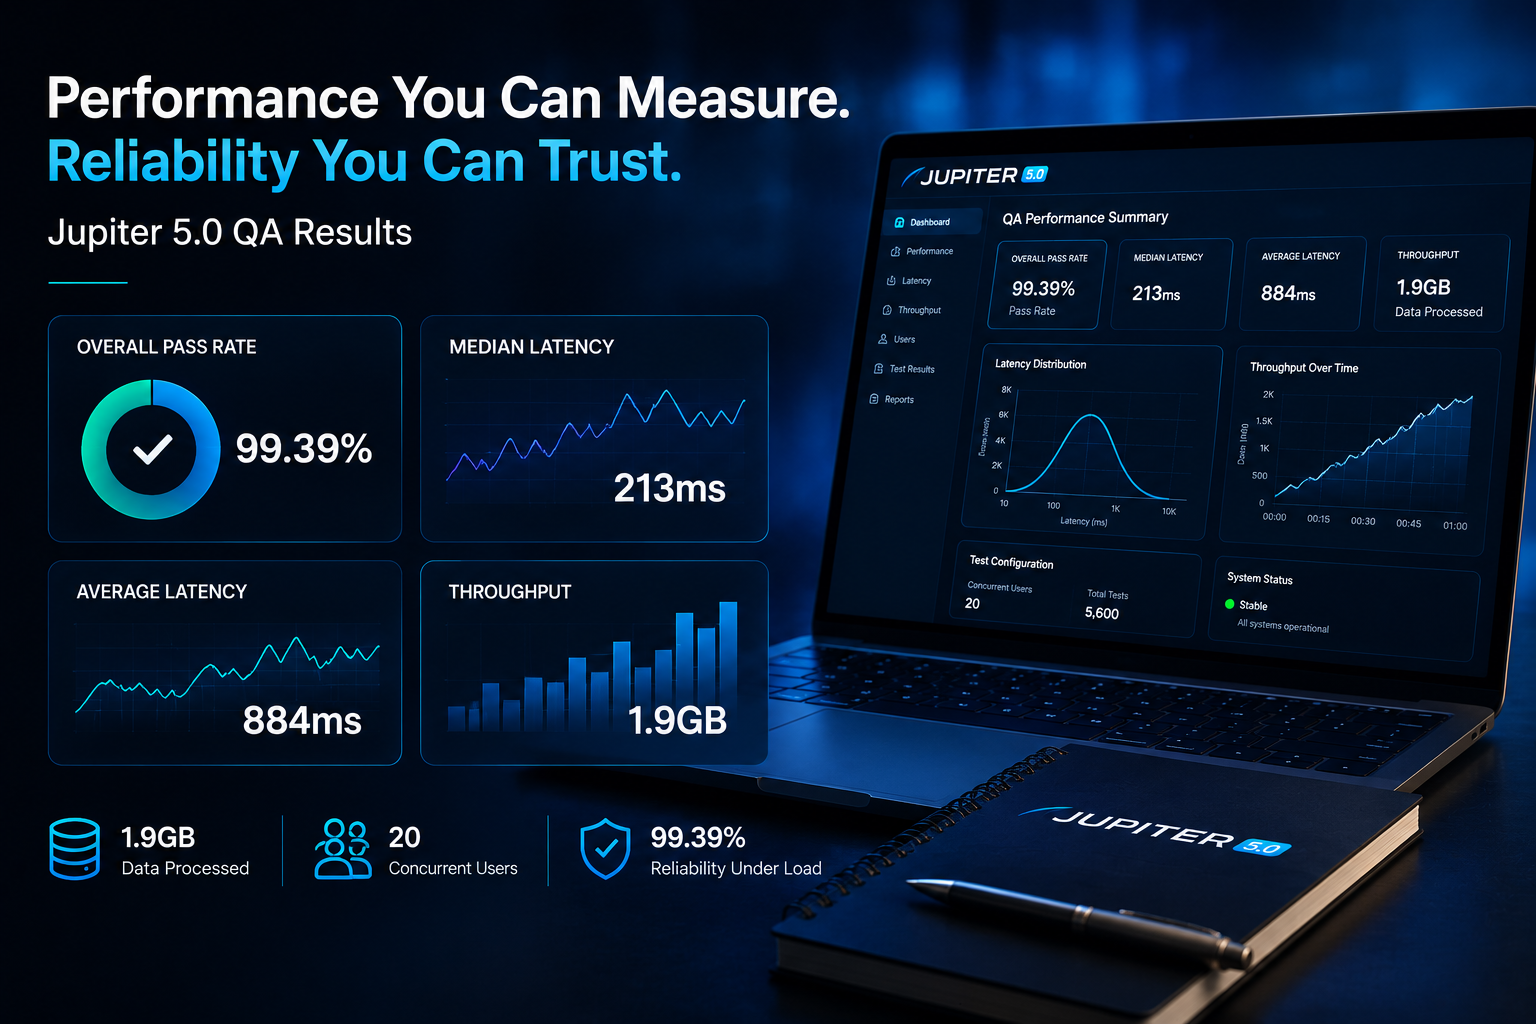
Overall pass rate: 99.39% — meaning roughly 34 checks failed out of 5,600.
That figure needs context before it means anything useful.
In a batch processing context — say, overnight fare file ingestion — a 0.6% failure rate is manageable. In a real-time pricing environment where each failed request could mean a stale fare reaching a distribution channel, the same number demands a harder look: which requests failed, when did they fail, and what triggers them?
The testing identified the primary failure source as a 307-redirect handling issue, accounting for all 33 observed failures. This is meaningful for two reasons. First, redirect mishandling in pricing APIs often surfaces during high-volume pushes to GDS or NDC channels — exactly the moments when reliability matters most. Second, and more importantly, the issue was caught and isolated before go-live, which is precisely what rigorous QA is designed to do.
The question for any team evaluating the platform is straightforward: has this been patched, and how was it verified?
II. Reading the Latency Numbers Honestly
The latency results are where the data gets interesting.
· Median latency: 213ms
· Average latency: 884ms
A gap this wide between median and average is not a rounding error. It indicates that while most requests resolve quickly — well within the threshold for interactive pricing workflows — a subset of requests are taking significantly longer, pulling the average up sharply.
For pricing teams, this distinction matters depending on how you work.
If your analysts are making reactive fare adjustments — responding to a competitor move, adjusting inventory ahead of a demand spike — the 213ms median is what they'll experience most of the time. That's fast enough to feel responsive.
If your workflows involve bulk operations — pushing thousands of fare updates simultaneously, running large market scans, or executing automated repricing rules — those outlier latencies are what you need to interrogate. Bulk operations hit the tail of the distribution, not the median.
The honest assessment: the platform performs well under typical interactive loads. The outlier behavior under high-volume operations deserves more scrutiny before committing to enterprise deployment.
III. What 1.9GB of Throughput Signals
The test processed 1.9GB of data across the full run — a reasonable proxy for the kind of throughput an airline pricing environment generates during active commercial periods.
Aviation demand creates non-linear load patterns. A normal Tuesday morning looks nothing like the first hour of a flash sale, a weather disruption across a hub, or the window immediately
following a competitor's capacity announcement. Systems that perform well at steady state sometimes degrade sharply when load concentrates.
The 20 concurrent virtual user model doesn't fully replicate a genuine demand spike — real spikes tend to be faster and less predictable than load testing can simulate. But sustaining 99.39% reliability across 1.9GB of concurrent traffic is a credible baseline. It suggests the architecture is designed for scale, not just optimised for benchmarks.
IV. What This Means Before You Commit
QA results tell you how a system behaves in a controlled environment. They don't tell you how it will behave integrated into your specific stack — your distribution setup, your repricing logic, your data volumes.
Before any enterprise rollout, pricing and revenue management teams should be asking:
On reliability: Has the 307 redirect issue been resolved? Can the vendor provide retest results? What failure modes exist beyond what QA captured?
On latency: What does tail latency look like under your specific bulk operation patterns? Can you run a proof-of-concept against your actual fare data volumes?
On scale: How does the platform behave at 50x or 100x concurrent users during a genuine demand event — not a simulated one?
On integration: How does the platform handle failures gracefully? If a fare update fails, what's the retry logic? What does the pricing analyst actually see?
V. The Bigger Picture
Pricing infrastructure has become a competitive variable in aviation, not just an operational necessity. The airlines with the fastest, most reliable pricing engines can respond to market changes before their competitors can react — and that speed compounds over time into measurable revenue advantage.
Jupiter 5.5's QA results suggest a platform that has been engineered seriously. The transparency around the redirect issue, the scale of the testing, and the latency profile all point to a system that can support enterprise airline operations.
The due diligence, as always, is in the details that QA summaries don't show you.
V. See How Jupiter 5.5 Performs Against Your Operations
QA benchmarks are a starting point. The conversation that matters is how the platform performs against your specific routes, volumes, and pricing workflows — not a controlled test environment.
If you're evaluating pricing infrastructure or questioning whether your current platform is holding your team back, we'd like to show you what Jupiter 5.5 looks like in practice. Request a demo and bring your real operational requirements. We'll show you exactly how the platform handles them.
See Jupiter on your own markets.
Talk to our team about what this means for your network.